Technology and Science · 24 June, 2026 · 3 min read
OpenAI And Broadcom Unveil Jalapeño LLM Inference Intelligence Processor
Jalapeño is OpenAI and Broadcom's first custom AI accelerator for LLM inference. Multi-year plan to deploy Jalapeño across data centers, aiming to reduce Nvidia dependence.
How credible/verified are the performance-per-watt results?.
7 of 9 outlets skipped it: microsoft is expected to buy 40% of chips..
15outlets compared
Same story, two versions
tap a side to read it in full
OpenAI
“early testing shows that the first-generation accelerator will deliver performance per watt substantially better”Read the original ↗
Confidence in efficiency depends on independent benchmarks, not just company-reported early testing.
Jalapeño for LLM Inference
OpenAI and Broadcom unveiled Jalapeño, described as OpenAI’s first “Intelligence Processor,” an accelerator architected for LLM inference and built “from the ground up” for current and future LLMs. OThe companies said the chip was co-developed from initial design to manufacturing tape-out in nine months, with engineering samples running ML workloads in the lab at production target frequency and power, including GPT‑5.3‑Codex‑Spark. OpenAI and Broadcom said early testing shows Jalapeño will deliver performance per watt “substantially better” than current state-of-the-art systems, while the architecture reduces data movement and balances compute, memory, and networking resources to raise realized utilization closer to theoretical peak performance.O
Broadcom’s silicon implementation and networking technologies, including Tomahawk networking silicon, were cited as part of how the platform is expected to reach large-scale production and deployment. The announcement also framed Jalapeño as the first chip in a multi-generation compute platform intended for gigawatt-scale data center deployments with data center partners beginning in 2026.
Leaders’ Claims and Delivery
OpenAI President and Co-Founder Greg Brockman said, “The world is moving to a compute-powered economy,” and added that Jalapeño is part of a long-term full-stack infrastructure strategy to make compute more abundant. OHardware program lead Richard Ho said, “We optimized the architecture around the kernels, memory movement, networking, and serving patterns that matter most for frontier AI models,” and said early testing indicates Jalapeño will execute key workloads close to the hardware’s theoretical limits. Broadcom President and CEO Hock Tan described the collaboration as “a fundamental commitment to scaling the physical infrastructure required for the next decade of AI,” and said it is “just the beginning of a multi-generation roadmap.”
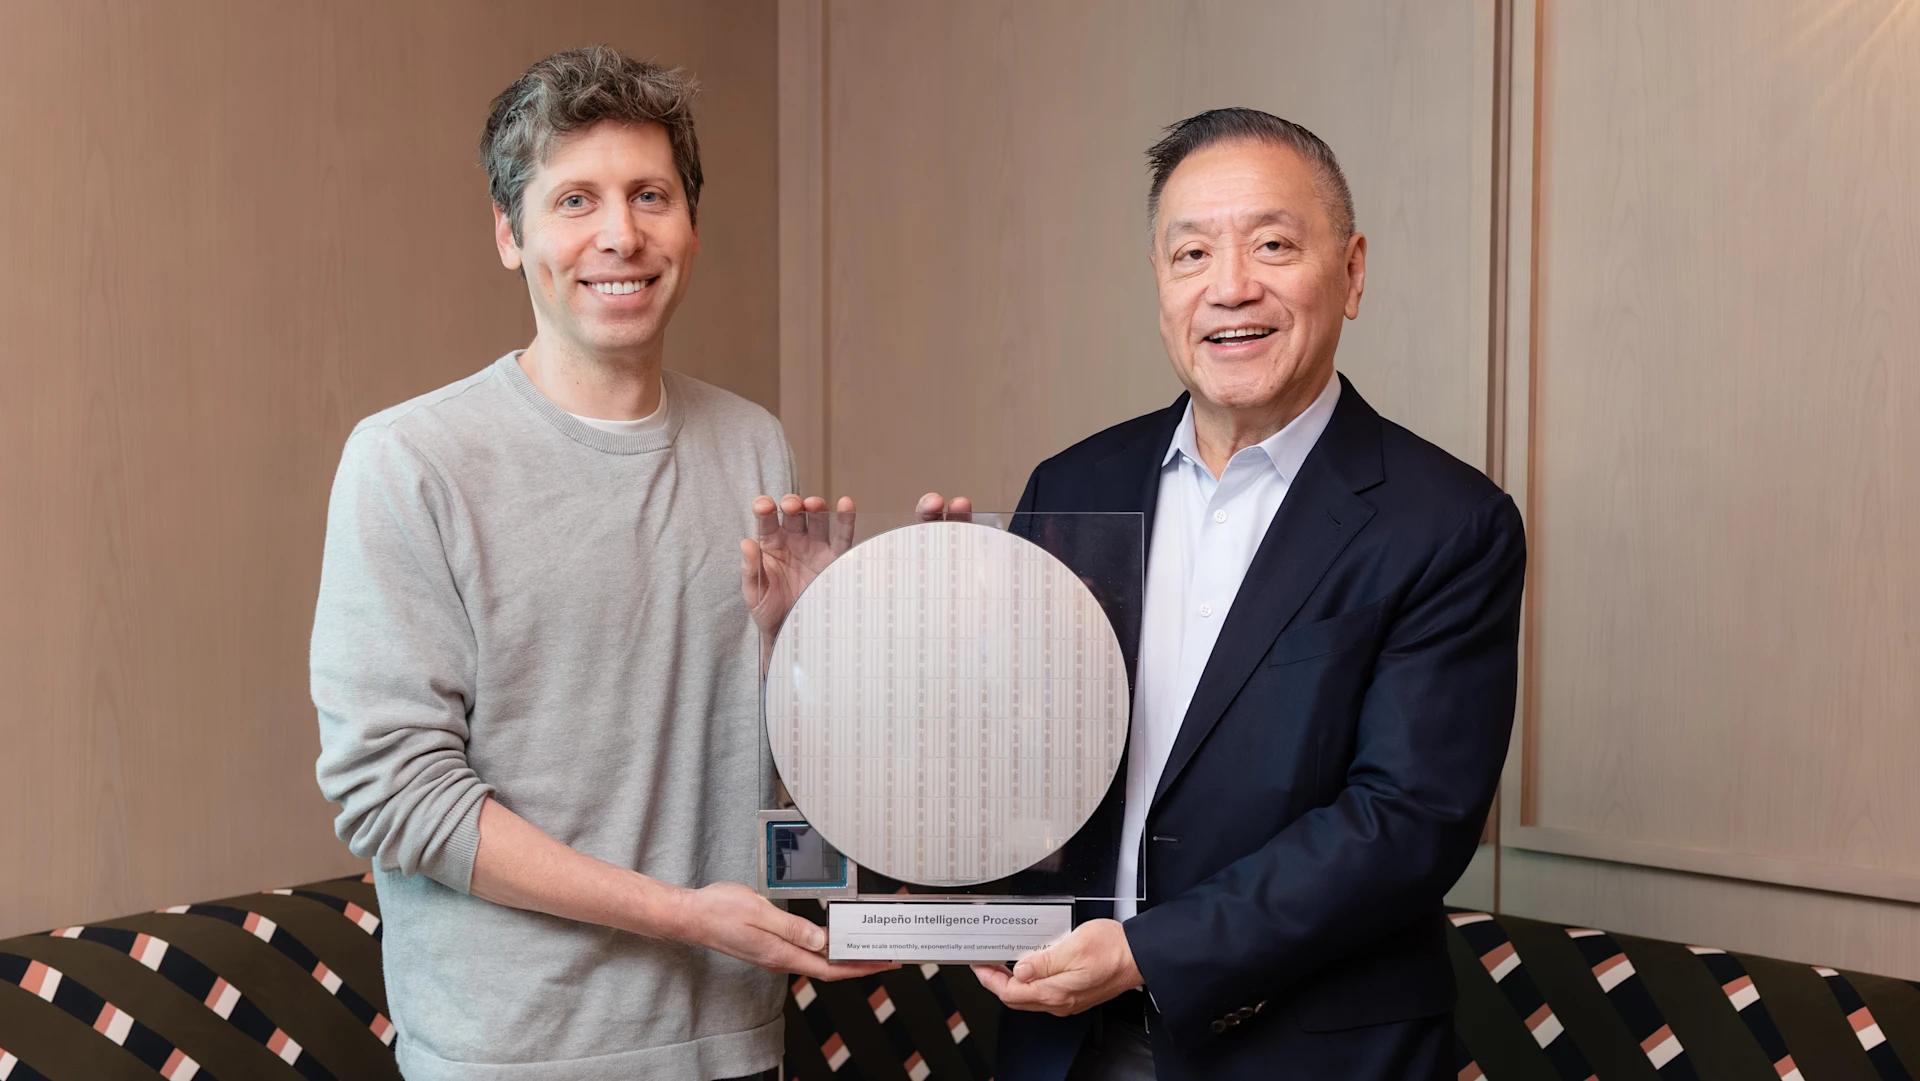
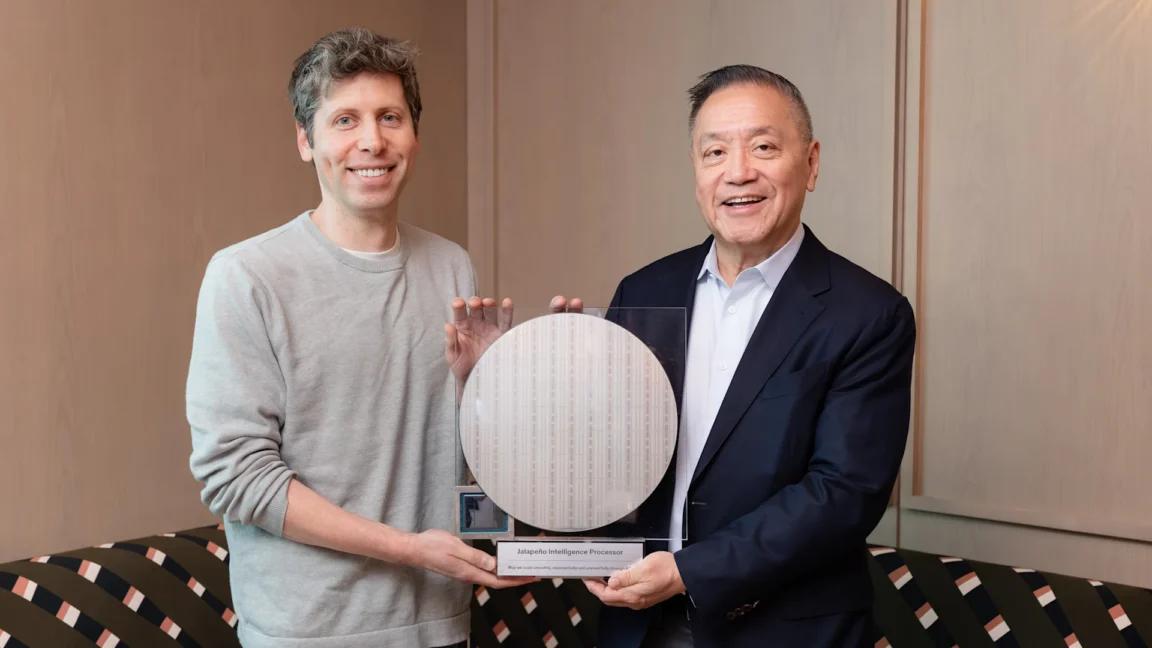
The Decoder reported that Broadcom CEO Hock Tan and President Charlie Kawwas handed the first wafer to OpenAI CEO Sam Altman and President Greg Brockman, marking the chip’s delivery for OpenAI. The Decoder also noted that performance claims are self-reported by OpenAI and that a technical report is supposed to follow, leaving which chips Jalapeño was tested against and under what conditions “unclear.”

Deployment Plans and What’s at Risk
OpenAI and Broadcom said Jalapeño is designed as a blank-slate for modern LLM inference, not a general-purpose accelerator adapted from earlier AI workloads, and that it is intended to support interactive LLM products at scale. OThe companies said the platform is designed to work with all LLMs guided by OpenAI’s insights into inference needs across current and future models, while also being informed by systems OpenAI runs across ChatGPT, Codex, the API, and future agentic products. OPulse 2.0 said Jalapeño was co-developed from initial design to manufacturing tape-out in nine months and expected to begin initial deployment by the end of 2026, expanding in the years ahead with data center partners.
Ars Technica reported that OpenAI claims “early testing shows that Jalapeño will deliver performance per watt substantially better than current state-of-the-art,” while also noting that OpenAI says it is not done measuring performance and that a “detailed technical report will be presented in the coming months.” OArs Technica added that the promise is specialization for current LLM inference needs in data centers, but that the chip’s performance is still tied to the forthcoming technical report and the companies’ continued measurement of results.